

Ho acquistato il Rasperry Pi Model 4B 8GB, ovviamente kit completo... 🙊
Cosa vuoi farci?
Bhè ho avuto giusto un paio di idee:
- Abilitato VNC per potermi collegare e navigare l'interfaccia grafica. caso mai servisse
- Abilitato SSH
- Installato Docker
- "Installato" portainer per gestire al meglio la mia installazione docker
- Follia 1 : "installato" Docker Registry e Jenkins come container
- Completa follia 2: ho aggiunto anche Apache Openwhisk
Prossimi passi?
Devo ancora studiarmi un modo per portare i miei progetti personali che scrivo in Golang sul docker installato sul raspy. Per questo ho installato il registry e jenkins, mi sembrano solo molto complicati per una cosa così "easy".
Staremo a vedere

Come ho costruito un database SQLite parsificando i dati dei pokemon disponibili sulle guide online
Partendo dall'esperienza del precedente articolo ( che vi riporto ) possiamo decidere di concentrarci su alcune pagine specifiche che contengono i dati che ci interessano.
In particolare voglio :
In particolare voglio :
- la lista completa dei pokemon di prima generazione
- la lista delle mn e di quali pokemon possono impararle
1. lista pokemon
Per estrarre la lista dei pokemon e crearne un json potete fare riferimento al precedente post.
Ne otterremo un json che potete trovare a questo indirizzo : github.com/pokedex_list.json
Ne otterremo un json che potete trovare a questo indirizzo : github.com/pokedex_list.json
2. mn e quali pokemon possono impararle
In modo del tutto simile al primo ho estratto i dati dalle pagine html della wiki di pokemoncentral. Per fare un esempio dalla pagina relativa al MN Taglio ( https://wiki.pokemoncentral.it/Taglio ) potete estrarre le informazioni necessarie con il seguente script:
In modo del tutto simile al primo ho estratto i dati dalle pagine html della wiki di pokemoncentral. Per fare un esempio dalla pagina relativa al MN Taglio ( https://wiki.pokemoncentral.it/Taglio ) potete estrarre le informazioni necessarie con il seguente script:
function getPkList(tbl, array){$(tbl).find('tr').each(function (i) { //loop on each tr in table// SKIP HEADERif(i===0) return;//CREATE POKEMON OBJECTvar poke = {};var $tds = $(this).find('td'); //get all td tagspoke.strid = $tds.eq(1).text(); //access first td and get text contentpoke.strid = poke.strid.replace('#','');poke.id = parseInt(poke.strid, 10);poke.imageUrl = $tds.eq(2).find('img')[0].getAttribute('src'); //access second td and get src attribute of the img tagpoke.name = $tds.eq(3).find('a')[0].text;poke.type1 = $tds.eq(4)[0].innerText;if($tds.eq(5)[0])poke.type2 = $tds.eq(5)[0].innerText;array.push(poke); //save object to the array});}
Il codice completo lo potete trovare a questo indirizzo: https://github.com/mcmaur/MyPokedex/blob/master/data/parser/parse_mn_list.js
Probabilmente dovrete adattarlo un poco a secondo della struttura delle altre pagine delle MN.
Una volta che lo avete eseguito su ogni MN vi troverete questo json:
https://github.com/mcmaur/MyPokedex/blob/master/data/MN_list.json

Struttura del database
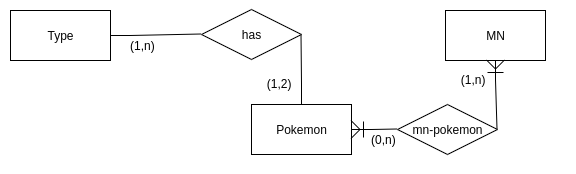
Cosa facciamo di questi due json? Bhè a sto punto studiamo una configurazione del database più adatta ai nostri dati e li importiamo.Risulta piuttosto evidente che il cuore è il POKEMON. Ogni pokemon ha 1 o 2 TIPI.
Ci sono 5 MN e per ognuna c'è una lista di pokemon compatibili. Per questo motivo il database avrà questa struttura:
Import dei dati in database
Nell'ambito della sperimentazione ho voluto provare Node.js .
Il codice contenuto nell'app.js fai i seguenti passaggi:
Il codice contenuto nell'app.js fai i seguenti passaggi:
- crea le tabelle del database
db.prepare(`CREATE TABLE IF NOT EXISTS \`types\` (\`id\` INT NOT NULL, \`name\` VARCHAR(100) NOT NULL,PRIMARY KEY (\`id\`));`).run();
- leggo il json e ciclo su ogni valore
let pokelist = JSON.parse(fs.readFileSync('./data/pokedex_list.json', 'utf8'));for (let index in pokelist) {
- verifico se il tipo è già presente altrimenti l'aggiungo
let t1 = -1, t2 = -1;for (let i in types) {if(pokelist[index].type1 === types[i]) t1 = i;if(pokelist[index].type2 === types[i]) t2 = i;}if(t1 === -1) t1 = (types.push(pokelist[index].type1))-1;if(pokelist[index].type2 !== undefined && t2 === -1) t2 = (types.push(pokelist[index].type2))-1;
- inserisco il pokemon nel database
const stmt = db.prepare('INSERT INTO pokemon(id, imageurl, name, type1, type2) VALUES(?, ?, ?, ?, ?)');
let info;
if(t2 === -1)
info = stmt.run(pokelist[index].id, pokelist[index].imageUrl, pokelist[index].name, t1, null);
- al termine del ciclo su tutti i pokemon salvo i tipi che avevo temporaneamente tenuto in un array
for (var i in types) {
const info = db.prepare('INSERT INTO types(id, name) VALUES(?, ?)').run(i, types[i]);
Adesso invece leggiamo i dati delle MN e importiamo anche quelli in maniera molto simile
let mnlist = JSON.parse(fs.readFileSync('./data/MN_list.json', 'utf8'));
mnlist = mnlist['MN'];
for (let key in mnlist) {
console.log("Id " + mnlist[key].id +': '+mnlist[key].name+'| '+mnlist[key].pokes);
const stmt = db.prepare('INSERT INTO mn(id, name) VALUES(?, ?)');
let info = stmt.run(mnlist[key].id, mnlist[key].name);
console.log("insert MN: "+info.changes);
let compatible_pokemons = mnlist[key].pokes;
for (let k in compatible_pokemons) {
const stmt = db.prepare('INSERT INTO mn_pokemon(mn_id, pokemon_id) VALUES(?, ?)');
let info = stmt.run(mnlist[key].id, compatible_pokemons[k]);
console.log("insert MN-POKEMON: "+info.changes);
}
}
FINITO: il codice completo lo potete trovare a questo indirizzo: https://github.com/mcmaur/MyPokedex/blob/master/app.js
Database scaricabile
Al termine avrete un database sqlite con tutti i dati. Il mio è disponibile a questo indirizzo: https://github.com/mcmaur/MyPokedex/blob/master/pokebase.db
Volete sapere qual'è il pokemon che può imparare più MN di tutti?
Facile! Eseguite la seguente query :
Volete sapere qual'è il pokemon che può imparare più MN di tutti?
Facile! Eseguite la seguente query :
select p.id, p.name, count(m.id) as mnlearnable -- , p.name, m.name-- select *from pokemon p
join mn_pokemon mnp on p.id = mnp.pokemon_idleft join mn m on mnp.mn_id = m.idgroup by p.id
order by mnlearnable desc
ed otterrete questi risultati:

Have Fun!

Quante volte avete pensato "perchè non c'è un API"?
Allora siete come me. Strani!
Quindi oggi vediamo come tirare fuori i dati da una pagina HTML.
Basta conoscere un poco di HTML, CSS e JQUERY.
La mia intenzione è di prendere i dati dei pokemon della prima generazione per farne un JSON. La pagina web che consulto in questo caso è questa:https://wiki.pokemoncentral.it/Elenco_Pokemon_secondo_il_Pokedex_di_Kanto
Quindi analizziamo un poco la pagina. Direi che si nota subito che ci sono 3 tabelle che contengono i dati che ci interessano.
Lavoriamo sulla prima per poter estendere con facilità il concetto alle altre visto che sono uguali.
Come tutte le tabelle la struttura è la seguente:
- table
- tr
- td
Selezioniamo in primis la tabella:
var table = $("table")[0];Impostiamo un loop per entrare in ogni singola riga:
$(tbl).find('tr').each(function (i) {Cerchiamo le colonne:
var $tds = $(this).find('td');Quindi estraiamo il dato della prima colonna:
poke.strid = $tds.eq(1).text();
Capito il meccanismo potete benissimo farlo per ogni colonna facilmente. La cosa più facile per un utilizzo successivo è quello di creare un oggetto per salvare i dati.Quello che ne risulta è il seguente:
function getPkList(tbl, array){
$(tbl).find('tr').each(function (i) {
// SKIP HEADER
if(i===0) return;
//CREATE POKEMON OBJECT
var poke = new Object();
var $tds = $(this).find('td');
poke.strid = $tds.eq(1).text();
poke.strid = poke.strid.replace('#','');
poke.id = parseInt(poke.strid, 10);
poke.imageUrl = $tds.eq(2).find('img')[0].getAttribute('src');
poke.name = $tds.eq(3).find('a')[0].text;
poke.type1 = $tds.eq(4)[0].innerText;
if($tds.eq(5)[0])
poke.type2 = $tds.eq(5)[0].innerText;
array.push(poke);
});
}
Quindi avendo una funzione ci basta prepare le strutture dati necessarie e chiamare la funziona sulla tabella che ci serve:
var pokes = [];
var tables = $("table");
getPkList(tables[0], pokes);
getPkList(tables[1], pokes);
getPkList(tables[2], pokes);
var json = JSON.stringify(pokes);
console.log(json);
Ora abbiamo scritto un codice javascript che dobbiamo solo eseguire nella console di sviluppo del browser con la pagina html aperta. Il codice completo lo potete trovare a questo indirizzo: https://github.com/mcmaur/MyPokedex/blob/master/data/parser/crawl_pokedex_list.js
Quello che otterremmo è un json così:

Oggi si è tenuto il Google I/O: la conferenza annuale in cui big G presenta i nuovi prodotti e le nuove funzionalità dei loro servizi.
Saltiamo i preamboli, quali sono questi tre annunci?
1.Smart Action Suggestion for Google Photo
L'app Photo vi proporrà delle azioni a secondo del contesto della foto. Per esempio condividere la foto con la persona che compare nella foto insieme a voi, oppure colorare una vecchia foto in bianco e nero. Una di queste azioni l'abbiamo tutti fatta spesso ma ora è più facile: convertire una foto in un documento. Google riconoscerà che è un documento e creerà automaticamente per voi un documento pdf.

2.AR Indication in Google Maps


Nelle foto vedete il tempo esatto per poterle rivedere da video live disponibile a questo indirizzo: https://www.youtube.com/watch?v=ogfYd705cRs
Saltiamo i preamboli, quali sono questi tre annunci?
1.Smart Action Suggestion for Google Photo
L'app Photo vi proporrà delle azioni a secondo del contesto della foto. Per esempio condividere la foto con la persona che compare nella foto insieme a voi, oppure colorare una vecchia foto in bianco e nero. Una di queste azioni l'abbiamo tutti fatta spesso ma ora è più facile: convertire una foto in un documento. Google riconoscerà che è un documento e creerà automaticamente per voi un documento pdf.

Per semplificarvi la vita come non mai, invece di cercare di capire il nome della strada dalle targhe sempre troppo distanti da voi, Google ha inserito la possibilità di visualizzare le indicazione per il vostro tragitto sovrapposte alle immagini provenienti dalla vostra camera. Il risultato è incredibilmente semplice ed efficace.

3.Automatic Appointment Assistant
Questa la prevedo difficile da spiegare. Praticamente quando voi chiederete al vostro Assistente Google di prenotarvi un appuntamento dal vostro parrucchiere di fiducia in un giorno preciso in una fascia di orario (es. mercoledi dalle 10 alle 12) i servizi di Google si attiveranno e faranno una chiamata al negozio e concorderanno l'appuntamento con la proprietaria. Facile no? Se non fosse che dietro non c'è un call center ma un assistente virtuale robotico (lo stesso del vostro google assistant) che parlerà in maniera naturale ma soprattutto dovrà capire le risposte dell'interlocutore con l'obiettivo di concordare una data ed ora che soddisfi sia le vostre necesssità che quelle del negoziante.
Quest'ultima funzionalità è incredibile, fa impressione scoprire i passi da gigante che hanno fatto il machine learning, il cloud natural processing ed il cloud to speech. Guardate il video su youtube: https://youtu.be/D5VN56jQMWM
Quest'ultima funzionalità è incredibile, fa impressione scoprire i passi da gigante che hanno fatto il machine learning, il cloud natural processing ed il cloud to speech. Guardate il video su youtube: https://youtu.be/D5VN56jQMWM

Nelle foto vedete il tempo esatto per poterle rivedere da video live disponibile a questo indirizzo: https://www.youtube.com/watch?v=ogfYd705cRs

Ma tu lo conosci Kotlin? Vieni a scoprire il linguaggio ad oggetti progettato da JetBrains con due workshop esclusivi organizzati dal GDG Torino!Che tu voglia sviluppare su Android al meglio o scoprire le potenzialità di questo nuovo linguaggio in un contesto inedito, questo è l’evento per te!
Due talk con due speaker d'eccezione: Mercoledì 4 aprile alle 18:30, presso la sede di Leva Engineering in Via Vincenzo Gioberti 18, prenderanno la parola Roberto Orgiu, GDE esperto di sviluppo Android e Roberto Franchini, CTO di Arcade.
https://www.meetup.com/it-IT/GDG-Torino/events/248799142/?eventId=248799142
LIVE ACTION:
Roberto Franchini:

LIVE ACTION:
Roberto Orgiu:


- extension function
- inline
- reified
- destructuring declarations
- dataclass
- component
- operator
- apply, let, with, run
Roberto Franchini:

- live coding session handling twitter stream & save on OrientDB

Sabato 24 marzo 2018 si terrà a Torino MERGE-it, prima esperienza di raduno nazionale tra le
diverse associazioni e community italiane che operano nel vasto e sfaccetato ambito delle
libertà digitali/ Un incontro inter-discitplinare per conoscere e far conoscere, scoprire,
approfondire e discutere su contenuti, strumenti, aspetti tecnici ed implicazioni culturali/
L’iniziatva coinvolge GFOSS.it, Industria Italiana Software Libero, Italian Linux Society,
LibreItalia, Mozilla Italia, Ninux.org, OpenStreetMap Italia, Spaghetti Open Data, Wikimedia
Italia e Ubuntu-IT, ed è rivolta soprattuto a coloro che hanno interessi trasversali tra software
libero, open data e cultura condivisa e vogliono cogliere l’occasione per atptprofondirli tutti
insieme.
Il programma si articola in otto sessioni parallele e tematiche dalle ore 10:00 alle 18:00.


Continuous delivery with Jenkins on DC/OS
Nel talk verrà fatta una panoramica sulle tecniche di continuous delivery/deployment, descrivendo come possono tornare utili per migliorare la fase di release e presentando un piccolo use case su come realizzare una semplice pipeline utilizzando jenkins, docker e dc/os.
Emanuele Maffeo
IoT with Kubernetes and Big data Descrizione:
Verrà descritta l' architettura di un applicativo per processare e servire dati provenienti da dispositivi IoT
Si parlerà di come integrare Kubernetes, CI con Gitlab, EFK, Nifi, Cloudera(Hadoop, Kafka, HBase) e molto altro
per creare un ambiente che permette di integrare il mondo dei Big Data con Cloudera e quello dei servizi con Kubernetes.
Mattia Bertorello
giovedì 15 marzo 2018
19:00 fino alle ore 21:00
Agile Lab
corso Trapani 16 · Torino

Analysis of blockchain-based startups and in particular on some of the most interesting solutions for this 2018.
Following this we will then talk about the legal environment in which the activities related to the blockchain navigate, the bodies involved and the most concrete examples.
mercoledì 14 marzo 2018
19:00 fino alle ore 21:00
Toolbox Coworking
Via Agostino da Montefeltro, 2 · Torino


Well no one knows why some important function disappear all of sudden, but to the internet now you can add this back again on your right-click menu. Simply copy this text :
[Nemo Action] Name=Make Link Comment=Create a link to %f Exec=ln -s %F %F.link Selection=s Extensions=any; EscapeSpaces=true
in a file and save it to ~/.local/share/nemo/actions/create-link.nemo_action

If you, like me, use Linux Mint 18 as OS and you want to install the latest version of Docker simply execute this commands:
sudo apt-get remove docker docker-engine docker.io
sudo apt-get update
sudo apt-get install apt-transport-https ca-certificates curl software-properties-common
curl -fsSL https://download.docker.com/linux/ubuntu/gpg | sudo apt-key add -
sudo add-apt-repository "deb [arch=amd64] https://download.docker.com/linux/ubuntu xenial stable"
sudo apt-get update
sudo apt-get install docker-ce
sudo groupadd docker
sudo usermod -aG docker $USER
Gist available at https://gist.github.com/mcmaur/5a0659c10af7bab9ab930e1531a82c2f

We both know that programming Android is mostly rewriting a number of times the same things.
Well here we are, save this page on the bookmarks and copy/paste when you need it.
Here some interesting images too:


Well here we are, save this page on the bookmarks and copy/paste when you need it.
FINDVIEWBYID
mWeatherTextView = (TextView) findViewById(R.id.tv_weather_data); READ JSON DATA
 JSONObject weatherdata = new JSONObject (JSONstring);
 JSONObject weather = weatherdata.getJSONObject("weather");
 String condition = weather.getString("condition");
BUILD URI AND CONVERT TO URL
 Uri builturi = Uri.parse(BASE_URL).buildUpon()
     .appendQueryParameter(QUERY_PARAM, param)
     .build();
 URL url = null;
 try {
   url = new URL(builturi.toString());
 } catch (MalformedURLException e) {
   e.printStackTrace();
 }
 return url;
EXECUTE ASYNCTASK
new GithubQueryTask().execute(githubSearchUrl);
ADD MENU IN TOP BAR
 @Override
 public boolean onCreateOptionsMenu(Menu menu) {
   MenuInflater inflater = getMenuInflater();
   inflater.inflate(R.menu.forecast, menu);
   return true;
 }

 @Override
 public boolean onOptionsItemSelected(MenuItem item) {
   if (item.getItemId() == R.id.action_refresh) {
     mWeatherTextView.setText("");
     loadWeatherData();
     return true;
   }
   return super.onOptionsItemSelected(item);
 }
EXPLICIT INTENT
 Intent intent = new Intent(this, SettingsActivity.class);
 startActivity(intent);
INTENT FOR EXTERNAL MAP
 Intent intent = new Intent(Intent.ACTION_VIEW);
 Uri uri = new Uri.Builder().scheme("geo").path("0,0").query("california").build();
 intent.setData(uri);
 if (intent.resolveActivity(getPackageManager()) != null) {
   startActivity(intent);
 }
SHARE INTENT
 Intent shareIntent = ShareCompat.IntentBuilder.from(activity)
  .setType("text/plain")
  .setText(shareText)
  .getIntent();
 if (shareIntent.resolveActivity(getPackageManager()) != null) {
  startActivity(shareIntent);
 }
ITEM IN THE ACTION BAR
 <item
   android:id="@+id/action_share"
   android:title="Share"
   android:orderInCategory="1"
   app:showAsAction="ifRoom"/>
ASYNCTASKLOADER
(it handles lifecycle) @Override
public Loader<String[]> onCreateLoader(int id, Bundle args) {
return new AsyncTaskLoader<String[]>(this) {
String[] weatherData = null; //Cache data
@Override protected void onStartLoading() {}//Check cache data and show progress bar then forceLoad()
@Override public String[] loadInBackground() {}//Get data from prefences or bundle and do network request
@Override public void deliverResult(String[] data) {}//save data in cache
};
}
USE PREFERENCEFRAGMENT
SHAREDPREFERENCES
 SharedPreferences sharedPreferences = PreferenceManager.getDefaultSharedPreferences(this);
 sharedPreferences.getBoolean("show_bass", true);
LISTEN TO SWYPE ON RECYCLEVIEW
 new ItemTouchHelper(new ItemTouchHelper.SimpleCallback(0, ItemTouchHelper.LEFT | ItemTouchHelper.RIGHT) {
   @Override
   public boolean onMove(RecyclerView recyclerView, RecyclerView.ViewHolder viewHolder, RecyclerView.ViewHolder target) {
     return false;
   }
   @Override
   public void onSwiped(RecyclerView.ViewHolder viewHolder, int swipeDir) {
     long id = (long) viewHolder.itemView.getTag();
     removeGuest(id);
     mAdapter.swapCursor(getAllGuests());
   }
 }).attachToRecyclerView(waitlistRecyclerView);
Here some interesting images too:


EVALUATION METRICS
The most simple and immediate metric is accuracy
accuracy = labeled correctly / all data
but it depends very much on the number of data in input so with different data is not comparable.
To resolve this we use the confusion matrix

Each row of the matrix represents the instances in a predicted class while each column represents the instances in an actual class (or vice versa).
Analyzing this data we can extract this two data:
- recall = how many times you get correctly? (similar to accuracy)
 true positive / ( true positive + false negative )
- precision = once predicted x, what is the probability that is really x?
 true positive / ( true positive + false positive )
CROSS VALIDATION
One round of cross-validation involves partitioning a sample of data into complementary subsets, performing the analysis on one subset (called the training set), and validating the analysis on the other subset (called the validation set or testing set).
The conventional validation works partitioning the data set into two sets of 70% for training and 30% for test for example.
Sklearn:
from sklearn import cross_validation
feature_train, feature_test, label_train, label_test = cross_validation.train_test_split (iris_data, iris_target, test_size=0.4, random_state=0)
[train]
pca.fit (feature_train)
pca.transform(feature_train)
svc.train(feature_train)
[test]
NO FIT (you want to use the same function as in the training)
pca.transform(feature_test)
svc.train(feature_test)
K-Fold:
 In k-fold cross-validation, the original sample is randomly partitioned into k equal sized subsamples. Of the k subsamples, a single subsample is retained as the validation data for testing the model, and the remaining k − 1 subsamples are used as training data.
So, we can explain also like this:
- repat k times
- pick 1 block of data as test
- train against the othe k-1 block
- test on testing set
- average final result
Sklearn:
from sklearn.cross_validation import KFold
kf = KFold(len(authors), 2)
for train_indices, test_indices in kf:
feature_train = [word_data[ii] for ii in train_indices]
feature_test = [word_data[ii] for ii in test_indices]
authors_train = [authors[ii] for ii in train_indices]
authors_train = [authors[ii] for ii in test_indices]
GridSearchCV:
Parameter tuning is the process of selecting the values for a model's parameters that maximize the accuracy of the model.
Scikit-learn provides an object that, given data, computes the score during the fit of an estimator on a parameter grid and chooses the parameters to maximize the cross-validation score.
By default, the GridSearchCV's cross validation uses 3-fold KFold or StratifiedKFold depending on the situation.
Sklearn:
parameters = { ‘kernel’: (‘linear’, ‘rbf’), C [1, 10])
svr = svm.SVC
clf = grid_search.GridSearchCV(svr, parameters)
clf.fit(iris_data, iris_target)
print clf.best_params_
PRINCIPAL COMPONENT ANALYSIS
PCA find a new coordinates system that is detained from the old one by translation and rotation only centering the data. The goal is to try making a composite feature that more directly probes the underlying phenomenon ( square footage + number of rooms → size ).
How to determine the pca:
The pca of a dataset is the direction that has the largest variance (variance = spread of data distribution) because it retains the maximum amount of original information. That is true because projecting the original data on the longer axis of the new coordinate system we can have a more spread data value and lose the minimum amount of information possible.
When to use:
- access latent feature
- dimensionality reduction
- visualize high dimensional data
- reduce noise
- use as preprocessing (reducing input for later algo [ eigenfaces] )
Sklearn:
from sklearn.decomposition import PCA
pca = PCA(n_components=2)
pcs.fit(data)
print pca.explained_variance_ratio_
first_pc = pca.components_[0]
second_pc = pca.components_[1]
x_train_pca = pcs.transform(X_test)
Every time I open Android Studio this come to mind is this
IMHO

Observer Pattern? MVC? MVP? MVVM? I don't know
IMHO

Observer Pattern? MVC? MVP? MVVM? I don't know
FEATURE SELECTION
Feature selection is the process of selecting a subset of relevant features (variables, predictors) for use in model construction. Feature selection techniques are used for four reasons:
- simplification of models to make them easier to interpret by researchers/users
- shorter training times
- to avoid the curse of dimensionality
- enhanced generalization by reducing overfitting
Add a new feature (feature extraction):
Feature extraction starts from an initial set of measured data and builds derived values (features) intended to be informative and non-redundant, facilitating the subsequent learning and generalization steps, and in some cases leading to better human interpretations.
- Use human intuition
- Code the new feature
- Visualize
- Repeat
Getting rid of a feature (feature selection):
There is an optimal number of feature that balances the bias and variance. So the process to find this point is called regularization.
There are two big univariate feature selection tools in sklearn: SelectPercentile and SelectKBest. The difference is pretty apparent by the names: SelectPercentile selects the X% of features that are most powerful (where X is a parameter) and SelectKBest selects the K features that are most powerful (where K is a parameter).
Lasso Regression:
One of this methods is Lasso regression that it introduces a penalty parameter for the number of feature, like this:
minimum SSE + |B|
So the formula implies that we find the perfect balance between the minimum sum of squared errors and the number of feature.
What also does is find the best feature because every “y” feature has a “m” coefficient so if you order your because by the m value you get a list of the most important feature.
Sklearn:
from sklearn.linea_model import Lasso
regression = Lasso()
regression.fit(features, labels)
regression.predict([2,4])
print regression.coef_

